1 min read
White Paper: Cabling as Architecture: The Physical Realization of L12 AI Clusters
Cabling is not the last step of an L12 deployment; it is one of the first architectural decisions. Every physical connection in an AI cluster is...
1 min read
Wiwynn
Updated on October 15, 2025
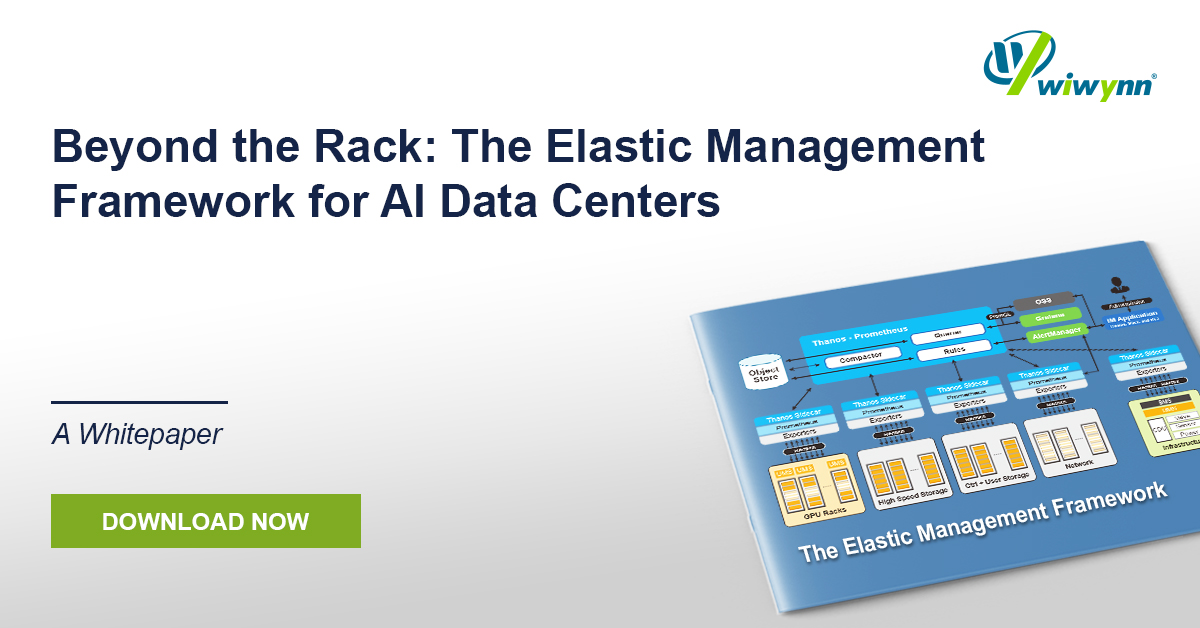
AI clusters using next-generation accelerators (e.g., NVIDIA GB200) push rack power density beyond 130 kW, making air cooling insufficient and driving adoption of direct liquid cooling (DLC). This whitepaper introduces Wiwynn’s Elastic Management Framework, a modular, scalable, interoperable architecture that unifies rack- and cluster-level monitoring and control across IT and facilities. The Wiwynn Universal Management System (UMS) enables autonomous rack-level protection and in-row CDU coordination, integrates heterogeneous sensors and controls via Redfish/Modbus/SNMP/analog/GPIO, and exports normalized telemetry to a Prometheus/Thanos platform with Grafana visualization and AlertManager response.
This paper first explains the Elastic Management Framework. It then details a production deployment showing faster leak isolation, safer power sequencing, and telemetry scaling to hundreds of endpoints. It presents lessons on IT/OT protocol standardization, modular rollout from rack to POD to data center, and joint IT–OT design for networking, security, data synchronization, and leak workflows to guide reliable, scalable operations.
Explore how Wiwynn’s Elastic Management Framework empowers AI data centers to achieve seamless orchestration from rack to facility. Download the full white paper to uncover strategies for managing high-density GPU clusters with advanced liquid cooling and intelligent infrastructure control.
1 min read
Cabling is not the last step of an L12 deployment; it is one of the first architectural decisions. Every physical connection in an AI cluster is...
This white paper presents a complete design and validation framework for next-generation high-power double-wide racks.
1 min read
This white paper presents a system-level perspective on how CPO technology can be integrated into scalable AI server architectures. It first...