1 min read
White Paper: Cabling as Architecture: The Physical Realization of L12 AI Clusters
Cabling is not the last step of an L12 deployment; it is one of the first architectural decisions. Every physical connection in an AI cluster is...
Wiwynn
Updated on December 31, 2025
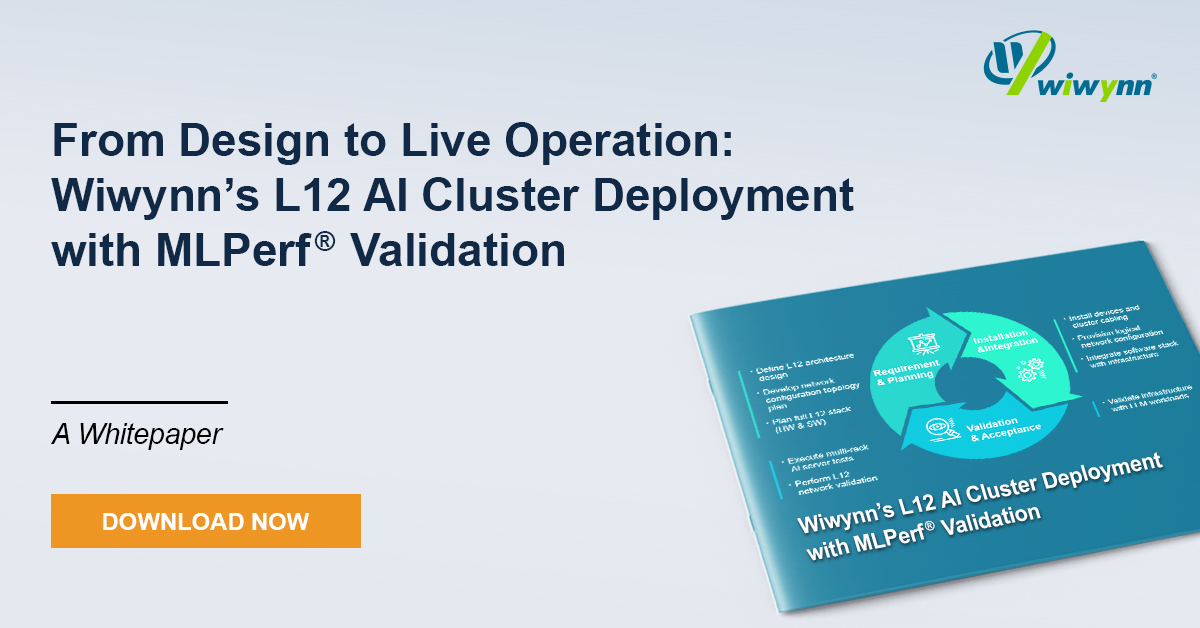
Deploying large-scale AI clusters introduces engineering challenges that extend well beyond the individual server rack. From liquid cooling integration to high-voltage power distribution and network topology design, the "Last Mile" of AI infrastructure presents multifaceted integration complexities.
This paper outlines Wiwynn’s L12 deployment methodology for the NVIDIA GB200 NVL72 platform. Using our Elastic Management Framework and validating performance via MLPerf® Training v5.1, we demonstrate how a structured deployment approach ensures production readiness, minimizing risks and accelerating time-to-market for AI clouds.
See how Wiwynn’s L12 methodology and Elastic Management Framework streamline NVIDIA GB200 NVL72 deployment with MLPerf®-proven results. Download the white paper to navigate integration complexities and ensure Day-1 readiness.
1 min read
Cabling is not the last step of an L12 deployment; it is one of the first architectural decisions. Every physical connection in an AI cluster is...
This white paper presents a complete design and validation framework for next-generation high-power double-wide racks.
1 min read
This white paper presents a system-level perspective on how CPO technology can be integrated into scalable AI server architectures. It first...