AI Infrastructure 

Wiwynn delivers high-resilience, elastic AI computing fabrics designed for the world’s largest Hyperscale Cloud Service Providers (CSPs). 
AI Infrastructure  |  Data Center Operations Optimization  |   Rack Integration   |    Green Innovation  

Open-Standards AI Infrastructure, Scale Without Limits.

AMD Helios™

AI at Scale. Built Open.

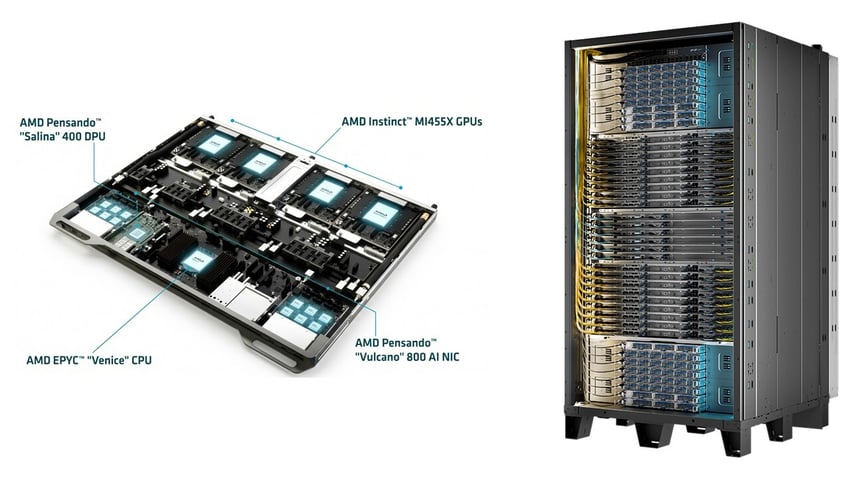
AMD Helios is a rack-scale compute platform purpose-built for next-generation AI factories. The system integrates 72 AMD Instinct™ MI455X GPUs, AMD EPYC™ Venice processors, and AMD Pensando™ Vulcano AI NICs to eliminate bottlenecks and maximize data movement and system efficiency.
With industry-leading memory capacity and bandwidth, Helios seamlessly handles larger models and extended context windows while delivering ultra-responsive performance for complex multi-agent workflows. Built on open standards including OCP, ORW, UALink™, Ethernet/UEC, Helios enables flexible scaling across data centers while optimizing power delivery, liquid cooling, and serviceability—serving as the ideal foundation for scaling industrial-grade AI.
Sec3

  • Leadership Compute Performance

    • Integrates 72 AMD Instinct™ MI455X GPUs into a unified in-rack compute domain, delivering the scale and flexibility needed for inference, training, fine-tuning, and multi-agent workloads.

    • Delivers up to 2.9 EFLOPS of OCP MXFP4 and up to 1.4 EFLOPS of OCP MXFP6/MXFP8 performance.

  • Industry's Best Memory

    • Large HBM memory capacity, implemented as a single load-store domain in the rack, helps support high-concurrency needs of agentic AI workloads.

    • Up to 31 TB HBM4 per rack with up to 1.67 PB/s aggregate memory bandwidth per rack.

  • Open Scale-Up and Scale-Out Architecture

    • Scale-Up: UALink over Ethernet (UALoE) connects GPUs through the in-rack switch fabric (single-switch-hop, multi-plane fabric, blind-mate rear cable cartridge; 6 AMD Helios switch trays).

    • Scale-Out: Standards-based Ethernet scales across racks and clusters; Ethernet/UEC-aligned scale-out via AMD Pensando "Vulcano" AI NICs; up to 3x800 Gb/s per GPU, or up to 43 TB/s rack bidirectional bandwidth.

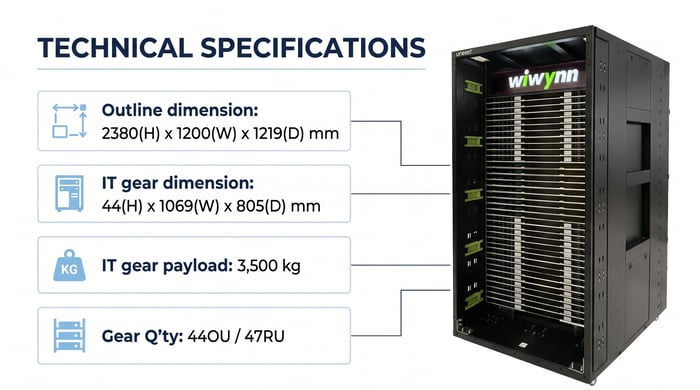
In‑house double‑wide Rack platform 

  • Ruggedized Hyperscale Foundation:A reinforced, anti-sagging chassis engineered for the mechanical stresses of mass global deployment. This architecture supports high-TDP AI clusters while integrating HVDC power paths and advanced signal integrity to eliminate bottlenecks.

  • Tailored for the AI Ecosystem: Fully aligned with OCP (Open Compute Project) ORW and Double-Wide standards to streamline brownfield and greenfield integration. Purpose-built for high-intensity AI training and inference at scale.
  • Deployment-Ready Flexibility: From factory-to-datacenter, our co-design and specialized packaging ensure system integrity during transit. Scalable by design, this platform evolves alongside your evolving workload demands.

Generated_Image


Why Choose Wiwynn?
Three Core Advantages
01 ⚙️

Global Delivery and Supply Chain Resilience

With a global manufacturing footprint and a robust service network, Wiwynn demonstrates exceptional supply chain agility. We effectively navigate international logistics challenges to ensure large-scale, high-efficiency, on-time delivery, empowering customers to rapidly deploy AI infrastructure worldwide.

02 📈

Driving Next-Generation Thermal Engineering Innovation

As AI platforms continue to drive higher power density, Wiwynn delivers industry-leading cooling solutions based on advanced thermal technologies. With highly integrated thermal architectures, thermal design limits are overcome while Power Usage Effectiveness (PUE) is continuously improved. Maximum performance is enabled, supporting customers in building efficient and sustainable green data centers for the future.

03 💡

Full-stack System Integration

From single nodes to hyperscale rack-level systems, Wiwynn possesses deep expertise in L12 integration and full system-level validation. We ensure that high-speed interconnect topologies within scale-up architectures are performance-optimized before leaving the factory, helping customers deploy ultra-bandwidth computing environments in record time.

Why Choose Wiwynn?Our Three Core Advantages

01

Global Delivery and Supply Chain Resilience

With a global manufacturing footprint and a robust service network, Wiwynn demonstrates exceptional supply chain agility. We effectively navigate international logistics challenges to ensure large-scale, high-efficiency, on-time delivery, empowering customers to rapidly deploy AI infrastructure worldwide.

02

Driving Next-Generation Thermal Engineering Innovation

As AI platforms continue to drive higher power density, Wiwynn delivers industry-leading cooling solutions based on advanced thermal technologies. With highly integrated thermal architectures, thermal design limits are overcome while Power Usage Effectiveness (PUE) is continuously improved. Maximum performance is enabled, supporting customers in building efficient and sustainable green data centers for the future.

03

Full-stack System Integration

From single nodes to hyperscale rack-level systems, Wiwynn possesses deep expertise in L12 integration and full system-level validation. We ensure that high-speed interconnect topologies within scale-up architectures are performance-optimized before leaving the factory, helping customers deploy ultra-bandwidth computing environments in record time.

Powering Boundless AI with Wiwynn

 The AI revolution is not won through hardware stacking, but through architectural orchestration. Wiwynn delivers intelligent, SLA-grade rack solutions that transcend raw specifications. We optimize every watt and every microsecond, transforming high-density GPU clusters into peak, sustainable computing output for the world’s most demanding data centers.

NVIDIA Vera Rubin

Global Scale. Precision Integration. Engineered for the Era of Terascale Computing.

Read More
NVIDIA Vera Rubin

Unleash Infinite Cloud Potential

 Customized Cloud Solutions: From R&D to Green Sustainability.